- Raw GSC exports show data but never suggest what to fix first.
- Parsing deduplicates URLs before any scoring can begin.
- Signal weighting ranks pages by opportunity size, not just performance.
- Cross-referencing on-page content completes any GSC-based diagnosis.
- Prioritized fix order, not the score number, drives real decisions.
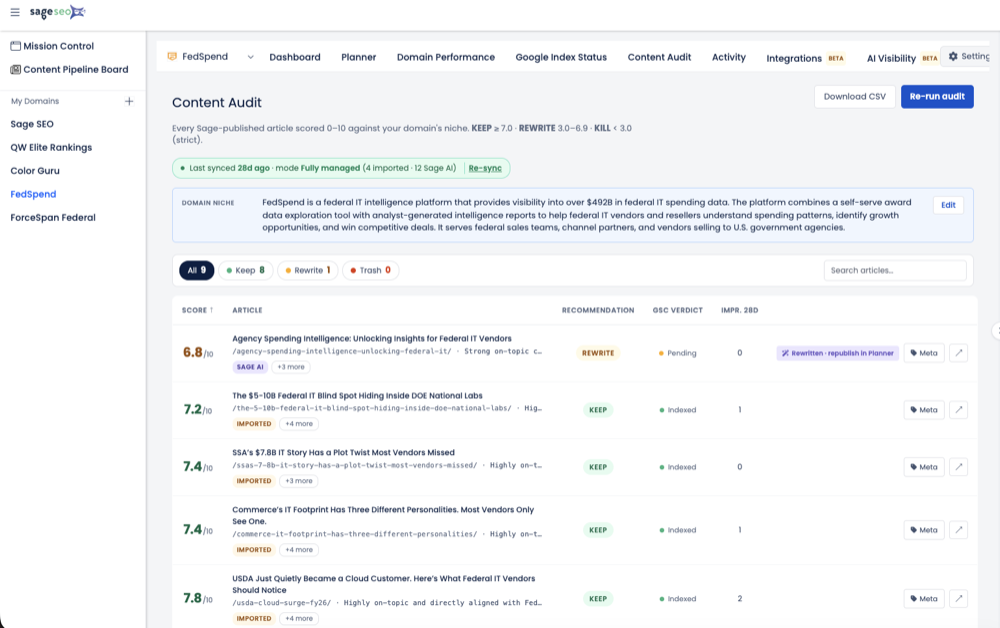
A client once emailed me a Google Search Console export at 11:47 p.m. with the subject line “what am I even looking at.” The file had 340 rows and zero explanation. By morning, after it ran through Sage SEO, that mess was a single on-page score and a ranked list of fixes. The client’s next question was the right one: “what actually happened in between?”
The Moment Before the Score: What a Raw GSC Export Actually Contains
A raw GSC export is a pile of disconnected facts about search behavior, not an opinion about your page. Pull one yourself and you’ll see rows of queries, impressions, clicks, CTR, and average position, each tied loosely to a page URL, exactly as Google’s own Search Console documentation describes the performance report. Nothing in that export tells you what to fix first.
I’ve watched smart marketing managers stare at a 500-row export for twenty minutes and give up, not because the data is wrong, but because it’s unprioritized. A page can show up for nineteen query variants, each with its own row. Here’s what’s actually sitting in that file before any scoring happens:
| Data point | What it tells you | What it doesn’t tell you |
|---|---|---|
| Impressions | How often Google showed the page for a query | Whether the page deserves to rank higher |
| Clicks | How often someone actually clicked through | Whether the content matched intent once they landed |
| CTR | The relationship between impressions and clicks | Whether a title tag or a weak snippet is the cause |
| Average position | Roughly where the page tends to rank | Which specific fix would move it |
That gap between “here’s the data” and “here’s what to do” is exactly the distance an SEO scoring tool has to travel. Everything from here is about closing it. (If you want the mechanics of how that export gets pulled and connected in the first place, I’ve already walked through what Sage SEO pulls from a connected Search Console property in a separate piece.)
Step One: Parsing Turns Rows Into Structured Signals
Parsing is the unglamorous step where chaos becomes a spreadsheet a computer can trust. The tool reads the export, maps each column to an internal field — page, query, position, CTR, impressions — and starts grouping rows that actually describe the same page.
This sounds trivial until you’ve lived the alternative. Early in my career, I ran a manual audit where I counted the same landing page three separate times because one version had a trailing slash, one had a UTM parameter attached, and one was https while an old row referenced http. The page’s real performance was split across three “different” URLs, and none looked particularly strong on its own.
A proper parsing step fixes this with two moves:
- Deduplication — multiple queries tied to one URL get consolidated into a single page-level record instead of staying scattered across dozens of rows.
- URL normalization — trailing slashes, tracking parameters, and protocol differences get stripped or standardized so the same page isn’t quietly scored twice under different identities.
Skip either step and you get a diluted, misleading picture. The page that looked “mediocre” across three fragmented rows was actually a strong performer once I added it back together — a mistake I now check for on every single audit.
Step Two: Signal Weighting — Not All Data Points Matter Equally
Every parsed signal gets a relative weight, because a high-impression page and a high-position page are opportunities of a completely different size. This is the step most users never see, and it’s where the “score” starts to form an opinion instead of just reporting facts.
Some signals point toward opportunity. A page pulling solid impressions but a weak CTR is practically waving a flag — people see it, something stops them from clicking. Other signals point toward risk: a page that’s been sliding in position over several weeks, even if it still gets a trickle of traffic, is a different kind of problem entirely.
The clearest way I’ve found to explain this to a skeptical client is a simple effort-to-reward comparison. I’m deliberately not giving you exact coefficients here — no scoring tool worth trusting publishes its precise formula, and I won’t invent one — but the directional logic looks like this:
| Page situation | Signal read | Effort-to-reward logic |
|---|---|---|
| Position 8–12, decent impressions | Opportunity — close to page one, visible demand exists | Small fix, plausible big jump |
| Position 40+, almost no impressions | Low priority — barely visible to begin with | Large fix, uncertain payoff |
| Position 15–20, falling trend | Risk — losing ground, worth investigating why | Moderate fix, time-sensitive |
That’s the heart of what a scoring tool is doing at this stage: not grading the page, but ranking how much attention it deserves relative to every other page in the export.
Step Three: Cross-Referencing On-Page Elements
Search performance data alone can’t tell you why a page underperforms, so this is the step where GSC signals meet the actual page content. Title tags, headers, and how closely the copy matches the query’s intent all get pulled in and compared against what the performance numbers already suggested.
This is the merge point, literally. A page with a weak CTR and a generic, keyword-free title tag isn’t a coincidence twice — it’s one problem showing up in two datasets. A page ranking in position 9 for a query that never once appears in its H1 is a different, equally diagnosable story.
I’m keeping this section high-level on purpose. The full breakdown of exactly which on-page factors get weighted and how is its own deep dive — I cover that territory in a companion piece on how ranking factors actually get calculated. What matters here is the principle: a score built only from GSC data is half a diagnosis. Cross-referencing content is what makes it whole.
Step Four: Compression — From Dozens of Checks to One Number
The single score you see at the end is a compressed summary of dozens of small pass/fail and scaled checks, not one master calculation. This is the aha moment most people miss entirely, and it changes how you should read the number.
Think of it less like a report card and more like a triage board in an emergency room. The board doesn’t tell you every patient is “fine” or “not fine” — it sorts who needs attention first. A page’s score works the same way: it’s a sorting mechanism built from many small checks, compressed into something scannable at a glance.
That compression explains a question nearly every client eventually asks me: why do two pages with the same middling score look nothing alike under the hood? One might be bleeding position on its core query while its on-page content is actually solid. The other might rank fine but have a title tag doing it zero favors. Same number, two completely different stories — which is exactly why the score always ships with prioritized recommendations attached, not just a digit on its own.
Step Five: Prioritization — What Gets Surfaced First and Why
The real product isn’t the score, it’s the order the fixes come in, ranked by estimated impact against estimated effort. This impact-versus-effort logic isn’t unique to any one tool — publications like Ahrefs and Moz have been writing about effort-versus-reward audit prioritization for years, and for good reason: it’s the only way to make an audit actionable instead of overwhelming.
I had an audit a while back where a client’s page sat at a thoroughly unremarkable score — nothing alarming, nothing impressive. Buried under that average number was one high-leverage issue: a title tag that didn’t contain the query the page was already ranking for in the high teens. Fixing a dozen smaller things on that page would have taken a week and barely moved the needle. Fixing that one title tag took an afternoon and was the obvious first move — not dramatic, just lopsided in the client’s favor on impact versus effort.
A clean way to think about how fixes should get sorted:
- High impact, low effort — surfaced first, almost always. Title tag rewrites, header mismatches, quick metadata fixes.
- High impact, high effort — surfaced second. Content rewrites, intent realignment, structural page changes.
- Low impact, low effort — nice to clean up, rarely urgent.
- Low impact, high effort — the stuff that shouldn’t eat your week.
Run your own export through GSC Momentum and you’ll notice the same thing I did: the recommendation list, not the number at the top, is where the actual decision-making happens.
Why This Matters More Than the Number Itself
Understanding the five-step pipeline is what turns a skeptical user into a confident one, because the mechanism is more trustworthy than the output alone. I get the hesitation. I’ve sat across the table from clients who’d been burned by a previous “audit tool” that spat out a number with zero context, and they treated every subsequent score — mine included — with suspicion. It’s the same instinct I described when I wrote about why I stopped trusting SEO tools that make you wait thirty seconds for a page to load — slowness and opacity both read as “hiding something,” even when they’re not.
Transparency about mechanism fixes that, even without exposing exact proprietary weights. You don’t need the precise formula to trust a process; you need to know the process is a reasoned pipeline — parsing, weighting, cross-referencing, compressing, prioritizing — rather than a black box spitting out a plausible-looking digit. That’s a reasonable bar for any automated tool to clear, and it’s the bar every “SEO scoring tool” should be held to before you let it drive client-facing decisions.
Here’s the practical difference it makes once a client actually understands the pipeline:
| Client’s posture | Black-box score, no explanation | Score with visible pipeline |
|---|---|---|
| Reaction to the number | Suspicion — “says who?” | Acceptance — they can see the logic |
| Reaction to recommendations | Cherry-picks the ones that feel right | Follows the priority order as given |
| Reaction to a low score | Assumes the tool is broken | Assumes there’s real work to do |
From Messy Export to First Monday-Morning Fix
Five steps, start to finish: parse the export into clean page-level records, weight each signal by opportunity or risk, cross-reference it against the actual page content, compress dozens of checks into one scannable number, then prioritize the fixes by impact against effort. The score is the headline. The ordering underneath it is the actual work product — the same ordering logic that eventually let me retire a slide-deck habit I describe in how I replaced my client reporting deck with score history instead. If you’ve got a GSC export sitting in a downloads folder right now, that’s the fastest way to see the pipeline for yourself instead of taking my word for it.