- Manual title editing at scale hides costly cannibalization risks
- Keyword cannibalization is easily triggered by unchecked bulk edits
- Prioritize pages with high impressions but low CTR first
- Run a three-step cannibalization guardrail before every batch publish
- Treat meta title optimization as a recurring workflow, not a project
Here’s a scar I earned about three years ago: I mass-edited a batch of about 40 “boring” meta titles for a B2B SaaS client in one afternoon, felt like a hero, and watched a page that had been quietly ranking on page one for a money keyword slide down over the next two weeks. I hadn’t broken anything technical. I’d done something dumber. I’d pointed two pages at the same phrase and let them fight. That afternoon is the whole reason I now treat any effort to bulk update meta titles as a workflow with a guardrail, not a chore to power through.
The Old Way: One CMS Tab, One Title, 400 Pages of Regret
The old manual routine meant exporting a URL list, opening each page in the CMS, editing the title field by hand, saving, and repeating hundreds of times.
My process for years looked like this. Pull a spreadsheet of URLs from a crawl. Sort by whatever felt worst. Then open tab after tab in the CMS, retype the title tag, hit save, close, next. On a site with 400-plus pages, that’s not a task. It’s a sentence.
The pain wasn’t just the tedium. It was the context-switching fatigue of bouncing between a spreadsheet and a CMS, losing my place, and re-editing a title I’d already touched. Worse, I was editing blind. I had no view of whether a given title was actually underperforming or just looked ugly to me.
Here’s the honest reason this stayed the default for so long: there was no easy way to see title performance data sitting next to the editing interface. You optimized on vibes.
This table is the routine I want to retire, and the hidden cost hiding inside each step.
| Manual step | What it looked like | The hidden cost |
|---|---|---|
| Export URL list | Crawl, dump to spreadsheet | No performance signal attached |
| Pick what to fix | Sort by gut feel | Fixing titles that were already fine |
| Edit in CMS | One tab per page | Context-switching, lost place, re-edits |
| Save and move on | No overlap check | Silent keyword cannibalization |
Why Did I Keep Putting This Off?
I deprioritized title-tag work for years because nothing told me which titles actually mattered, so it always lost to more urgent tasks.
When every title looks equally editable, none of them feel urgent. I couldn’t point to a page and say “this title is costing us clicks” with evidence, so the whole project kept sliding down the backlog behind things with a clearer payoff.
I was rewriting titles based on taste, not on data. A title that read awkwardly to me might have been pulling a perfectly healthy click-through rate. I had no way to know. Without impressions-and-clicks context, “bad title” just meant “title I don’t like today.”
So the nagging doubt was always the same. If I couldn’t tie the hours to a measurable outcome, why would this beat the thing on fire in my inbox? It never did. That’s exactly the gap a performance-data-first approach to on-page work is built to close.
The Mistake: Mass-Editing Titles Without a Cannibalization Check
My worst title-tag mistake was batch-rewriting a set of underperforming titles to include a target phrase without checking whether another page already owned that phrase.
The story in full: I had a cluster of maybe 40 thin, generic titles on that SaaS client’s resource section. I decided they all needed a strong commercial keyword baked in, the kind of phrase that already had a dedicated pillar page ranking for it. I didn’t check that. I just ran the batch.
Within about two weeks, the pillar page that had been sitting around position 6 for that exact phrase started wobbling. Then it dropped. Nothing had changed on the pillar page itself. What changed was that I’d handed Google three or four other URLs on the same domain suddenly shouting the same keyword.
I diagnosed it the way you usually catch this: I noticed two URLs from the same site flickering in and out of the results for overlapping queries where, a month earlier, only the pillar had shown up. Classic keyword cannibalization, self-inflicted, at speed.
The lesson stuck because it’s structural, not personal. Bulk editing multiplies your mistakes with exactly the same efficiency it multiplies your wins. If there’s no check built into the process, speed just gets you to the regression faster. This is the same trap I describe when I write about rehabilitating a single underperforming page — one clean fix beats ten fast ones that collide.
Skip the spreadsheets. Start Sage SEO free.
See how AI content ops transform your agency workflow in minutes.
Here’s what the damage actually looked like, query by query.
| Query | Before the batch edit | After the batch edit |
|---|---|---|
| Primary commercial phrase | Pillar page, stable ~pos 6 | Pillar drops; resource pages flicker in |
| Long-tail variant | One clear owner | Two internal URLs alternating |
| Brand + phrase | Pillar page | Diluted across the cluster |
The Guardrail I Run Before Any Bulk Title Change
Before I push any batch of title edits now, I cross-check every proposed target phrase against pages that already rank for or target that same term.
Conceptually it’s simple. I group the proposed titles by target phrase or topic, then flag any phrase that already has an established owner on the site. If a new title wants a keyword a pillar page is already winning, that title gets reworked toward a more specific long-tail angle or pulled from the batch entirely.
This is non-negotiable now. Not a nice-to-have, not a “when I have time” step. It’s the checkpoint that stands between “efficient” and “efficiently wrong.” Google has said plainly that it generates titles from more than just your title tag, so I’m not the only variable — but self-cannibalization is the part fully within my control, and I refuse to reintroduce it. You can read Google’s own explanation of how it generates page titles for the full picture.
What surprises people: the guardrail doesn’t slow you down. Once it’s a habit, it’s a filter that runs in seconds, not a return to one-by-one manual review. Run these three checks before every push.
- Group by target phrase. Sort proposed titles so identical or near-identical keywords cluster together.
- Match against current owners. Flag any phrase a page already ranks for or was built to target.
- Resolve before publishing. Differentiate the intent, narrow to a long-tail, or drop the edit — then push the clean batch.
How Does the Bulk Title Workflow Work Now?
Today the workflow starts from real click-through data, prioritizes pages with impressions but weak CTR, applies the cannibalization guardrail, and pushes approved edits in batches.
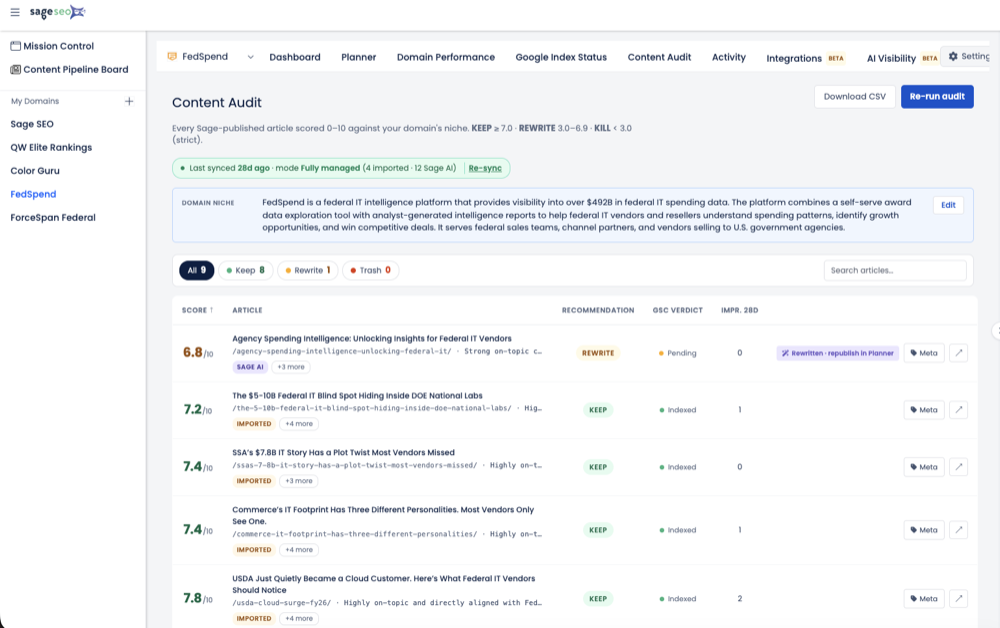
The single biggest change is where the work begins. I no longer start from opinion. I start from a title tag audit that puts click-through performance next to each page, so I’m reviewing sitewide recommendations informed by how titles actually perform in the results — not how they read to me on a Tuesday.
Prioritizing by opportunity, not alphabet
Then I prioritize by opportunity. The pages I touch first are the ones with healthy impressions but weak click-through — the titles Google is already showing to people who then scroll right past. Editing alphabetically or by page type is how you burn an afternoon on pages nobody was going to click anyway. Pulling that impressions-and-clicks signal is exactly what a tool like Search Console momentum tracking is for.
| Page bucket | Signal | Priority |
|---|---|---|
| High impressions, low CTR | Seen, not clicked | Fix first |
| High impressions, healthy CTR | Working already | Leave alone |
| Low impressions, low CTR | Visibility problem, not a title problem | Defer |
Review, guardrail, push
From there it’s batches. I review the recommendations in groups, run the cannibalization check across the group, then push the approved changes together instead of one lonely CMS tab at a time. The felt difference is enormous: less tab-switching, far less guessing, and real confidence that each edit maps to an actual performance gap.
One thing I will not do is hand you a fake number. I’m not going to claim a specific CTR-driven title tags lift from this process, because the honest improvement I can vouch for is in workflow efficiency and decision quality, not a guaranteed percentage. If you want the writing-craft side of that equation, my take on what actually moves click-through in the SERP snippet is the companion to this piece. And it’s worth remembering Google rewrites a large share of titles anyway — Zyppy’s large-scale title-rewrite study found the search engine changes displayed titles a majority of the time — so your job is to give it a strong, unambiguous signal, not a perfect billboard.
Old way versus now, side by side
| Dimension | Old manual way | CTR-driven bulk way |
|---|---|---|
| Starting point | Gut feel | Click-through data |
| Order of work | Alphabetical / random | Weak-CTR, high-impression first |
| Editing | One tab per page | Reviewed in batches |
| Cannibalization | Discovered after the drop | Caught before publish |
What I’d Tell Someone Starting This Today
Start from click-through data, build the cannibalization check in from day one, batch by priority, and treat titles as an ongoing loop rather than a one-time cleanup.
If I could hand my younger self a checklist before that 40-title afternoon, it would be short and it would be strict.
- Audit against performance, not opinion. Rank titles by impressions and click-through before you rewrite a single one.
- Install the guardrail immediately. Don’t learn cannibalization the way I did, with a two-week ranking slide.
- Batch by priority. High-impression, low-CTR pages earn your first hour; convenience earns nothing.
- Make it recurring. Search behavior shifts, so titles need periodic revisiting — this is a workflow, not a project.
Follow that and you skip the scar entirely. The whole point of learning to work from real-time performance data is that the machine watches for the overlaps you’ll inevitably miss at 4pm on a Friday.
Speed Is Only an Asset If Something Catches Your Mistakes
I don’t romanticize the manual era. It was slow, it was dumb, and it hid the cannibalization I caused until the rankings told on me. But I also refuse to worship speed for its own sake. Bulk editing without a guardrail isn’t a workflow — it’s a faster way to break things you already had working. The version that works now isn’t just quicker. It’s quicker with a filter in the middle, and that filter is the entire difference between shipping 40 improvements and shipping 40 collisions. Move fast, sure. Just make sure something is checking the overlaps while you do.