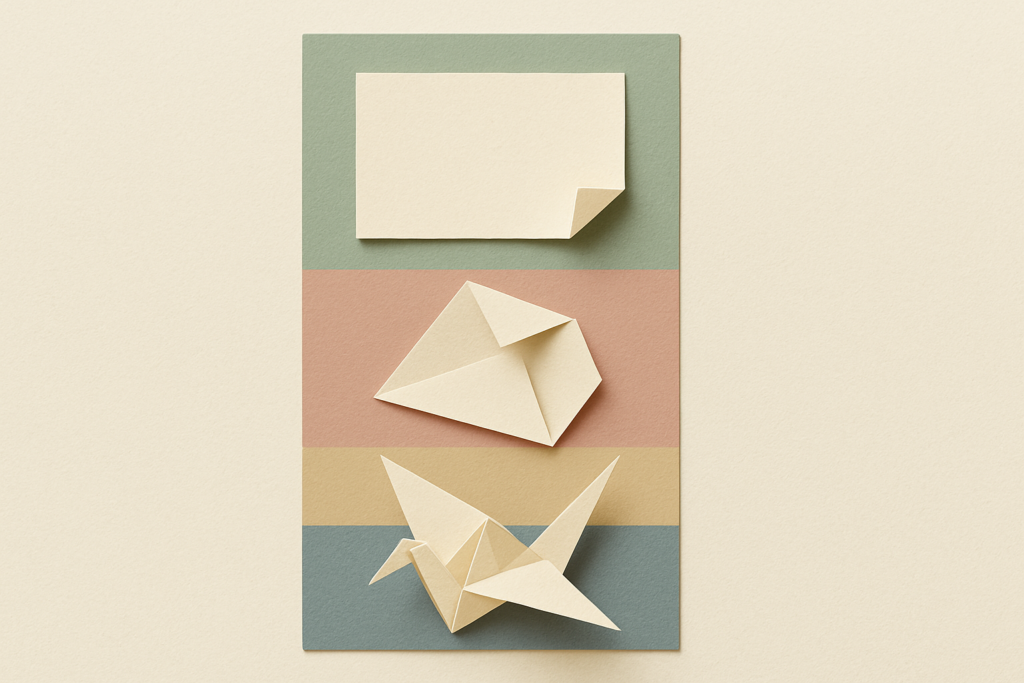
- Sage Writer runs four stages, not a one-shot prompt
- SERP intent is classified before any drafting starts
- Brand voice parameters apply during generation, not after
- Self-critique loop flags structure and logic errors pre-publish
- Schema and internal links generate from the draft's own context
I spent four years running an editorial pod for agency clients: a strategist, a writer, an editor, a technical SEO, and me doing the interlinking nobody wanted to own. When I finally put Sage SEO’s AI Writer in front of that same workflow, the surprise wasn’t the draft quality. It was watching schema and internal links show up already correct, because the system never treated them as a separate job. That’s the whole story of how this tool works, and it’s worth explaining properly instead of waving at “AI magic.”
What “AI Writer” Actually Means Here (And What It Doesn’t)
Sage Writer isn’t a prompt box that spits out a draft in one shot — it’s a four-stage pipeline, and the draft is only stage two. Most tools I’ve tested over the past five years are a ChatGPT wrapper with a nicer UI: feed it a keyword, get 1,200 words, and you’re on your own for structure, internal links, and schema. I burned three months in 2023 running exactly that workflow, and the meta-title cleanup it created afterward ate more hours than the drafting saved.
The four stages below: reading the search signal, drafting inside a brand persona, a self-critique loop, and generating schema and internal links from the same understanding that wrote the sentences. None are plugins bolted onto a finished draft.
| Step | Generic AI Wrapper Tool | Sage Writer Pipeline |
|---|---|---|
| Structure decision | Guessed from the prompt alone | Set by SERP and intent analysis before drafting starts |
| Brand voice | Style-guide edit after generation | Persona parameters applied during generation |
| Quality control | Human skim or nothing | Automated self-critique pass, then human review |
| Schema + internal links | Separate plugin or manual pass | Generated from the draft’s own topic map |
How Does Sage Writer Read a Search Signal Before It Writes a Word?
It classifies intent and maps the current SERP before a single sentence gets drafted, which is what decides whether the output should be a listicle, a guide, or a comparison piece. I’ve watched intent-blind tools write a 2,000-word narrative guide for a query where every ranking result was a comparison table — technically fluent, commercially useless.
This stage looks at three things: what intent the query carries (navigational, commercial-investigation, informational), what structure the top-ranking pages already use, and what those pages leave out. That gap analysis is the same discipline behind clustering keywords by intent rather than volume alone — the writer runs that clustering per article, not once a quarter in a spreadsheet.
Why This Prevents Intent-Mismatched Output
Skipping this step is the most common failure mode I see in simpler tools. A query can look identical in volume and be totally different in intent — “best CRM for agencies” wants a comparison table, “what is a CRM” wants a definition — and a tool that doesn’t separate the two writes the wrong shape of article every time.
| Signal Sage Writer Reads | What It Reveals | Structural Decision Triggered |
|---|---|---|
| Query phrasing (“how does X work”) | Informational / investigation intent | Mechanism-driven explainer, question H2s |
| Dominant SERP format | What Google already rewards | Table-heavy, listicle, or narrative guide |
| Content gaps in top results | Where competitors under-deliver | Added H3s or sections competitors skip |
How Does an AI SEO Writer Maintain Brand Voice at Scale?
Brand voice is set as generation parameters — tone, vocabulary constraints, point of view — applied while the draft is written, not corrected in a second pass. I’ve edited enough AI drafts by hand to know the difference between those two approaches is the difference between a two-minute skim and a forty-minute rewrite.
Here’s the distinction that matters: a style guide checklist applied after generation catches surface issues — banned words, passive voice, wrong pronoun. It can’t fix a paragraph that’s structurally generic, the kind that reads like it could sit on any SaaS blog with the logo swapped out. Persona constraints in Sage Writer shape sentence-level choices during drafting: sentence length variation, whether the piece argues in first person or stays corporate-neutral, which examples it reaches for. That’s a different intervention point entirely.
I ran a version of this manually for two years before any of this existed. A B2B SaaS client I advised had five writers producing content, and keeping one consistent voice meant an editor doing nothing but voice passes — 15 to 20 hours a month just smoothing tone. That’s the labor a persona-constrained drafting stage absorbs by not introducing the inconsistency in the first place, not by editing it out afterward.
What Persona Configuration Actually Constrains
- Point of view — first person operator voice versus third-person corporate voice
- Vocabulary — banned jargon, preferred terminology, reading-level ceiling
- Sentence rhythm — whether the brand favors short punchy claims or longer explanatory prose
- Example sourcing — whether the brand leans on data citations, client anecdotes, or both
None of that replaces a founder’s judgment about whether a specific line sounds “off.” It just means the editor’s job shifts from rewriting every third sentence to spot-checking for the stuff a pattern can’t catch — which is most of what the next section covers.
Inside the Self-Critique Loop: What Catches Errors Before You Ever See Them
Before a draft reaches a human, the system evaluates its own output against a defined set of criteria — redundancy, structural logic, intent alignment, internal contradiction — and revises against those flags in an iterative pass, not a single generation. This is the stage that most explains why the output doesn’t read like a first draft.
What it checks for:
Skip the spreadsheets. Start Sage SEO free.
See how AI content ops transform your agency workflow in minutes.
- Whether the piece actually answers the query it was built for, section by section
- Repetition — the same claim restated three different ways across H2s
- Structural logic — does each section build on the last, or do they just sit next to each other
- Internal contradiction — a stat or claim in paragraph two that disagrees with paragraph eight
I want to be straight about the limit here, because overselling this is exactly how trust gets burned. The critique loop catches structural and logical issues reliably. It does not verify niche factual claims against the live world — a pricing figure, a regulatory detail, a competitor’s current feature set. That’s the boundary of what any model can self-verify without an external source feeding it ground truth. Google’s own guidance has stayed consistent on this since its 2023 clarification that AI-produced content isn’t penalized for how it was made — the quality bar is whether it’s helpful and accurate, which means the accuracy burden never disappears just because drafting got faster.
I learned this the expensive way auditing a client site that had let three AI-assisted posts go live with an outdated statistic nobody caught for six weeks. The structure was flawless. The number was wrong. That gap is where the next stage of review has to sit, and no critique loop closes it alone.
How Is Schema Markup Added to AI-Generated Articles Without Bolting It On?
Internal link suggestions and schema markup are both generated from the same semantic map the system built while writing the draft, not matched against keywords after the fact. This is the part of the pipeline I find hardest to explain to people who haven’t watched it work, because it sounds like a minor sequencing detail. It isn’t.
The common alternative — write the article, then run a separate SEO plugin or manual pass to insert links and schema — treats the article as a finished object being decorated. The plugin doesn’t know what the third paragraph argues; it just pattern-matches anchor text against a sitemap. I’ve watched that produce internal links that are topically close but contextually wrong, the kind that make a reader click through and immediately bounce because the destination doesn’t answer what the anchor text implied.
Because Sage Writer generates links from its own understanding of what the draft covers, links tend to land where the argument needs support — the same principle behind rebuilding topical authority on an old site through automated internal linking rather than a one-time cleanup project. Schema works the same way: Article, FAQ, and HowTo markup get generated from the content’s actual structure — four sequential steps earns HowTo schema, a genuine Q&A section earns FAQ schema. Nothing gets forced into a type the content doesn’t actually have.
Where Does Human Review Fit in an AI Content Workflow?
A human still reviews every piece before it publishes, checking factual claims, brand judgment calls, and competitive positioning nuance that no automated pass can own. Plainly: this pipeline compresses a five-person editorial process, it does not eliminate one.
Here’s what compresses versus what stays human on every team I’ve set this up for:
| Editorial Role | Pre-Pipeline Workload | Status After Sage Writer |
|---|---|---|
| Keyword/intent researcher | Manual SERP review per article | Largely automated in stage one |
| Voice editor | Line edits on every draft | Mostly automated via persona config |
| Internal linking specialist | Manual link-mapping pass | Automated, spot-checked by editor |
| Fact-checker / subject reviewer | Full manual review | Still fully human |
| Strategic editor (positioning, CTA) | Full manual review | Still fully human |
The roles that compress are mechanical — the researcher cross-referencing SERPs, the editor smoothing tone, the specialist mapping anchor text by hand. The roles that stay human are judgment calls: is this claim true, does this positioning undersell us against a specific competitor, would our actual customers object to this framing. I’d trust it less if a vendor claimed otherwise. A disciplined pipeline with a human checkpoint produces more consistent output than either a fully manual team or a fully autonomous one — the same reasoning I used building a full framework for auditing content against AI-generated search results.
What This Looks Like in Practice
Picture a Tuesday scenario I’ve seen play out a dozen times. A query spikes in Search Console impressions — the kind of signal I’ve turned into a same-day published article before. Here’s the condensed sequence from there:
- The spike gets flagged and classified for intent — commercial, informational, or navigational.
- Stage one maps the current SERP and decides the piece needs a comparison table, not a narrative guide.
- Stage two drafts inside the brand’s configured persona — first person, short sentences, specific examples.
- Stage three runs the self-critique pass, flags one redundant paragraph, and tightens it.
- Stage four generates FAQ schema and three internal links from the draft’s own topic coverage.
- A human editor reviews for factual accuracy and positioning, approves, and publishes.
That’s a condensed, illustrative walkthrough — not a case study with numbers attached — but it’s the shape of the loop every time, regardless of topic.
The Loop Is the Product, Not Any Single Draft It Produces
If you take one thing from this, take this: judging an AI writer by one sample draft is like judging a factory by one unit off the line. The pipeline design — intent-first structure, persona-constrained drafting, honest self-critique, and schema built from the same understanding that wrote the sentences — determines whether article 200 is as consistent as article one. A single great output proves nothing. A system that holds its shape at scale, with a human still checking what matters, is the only claim worth evaluating.